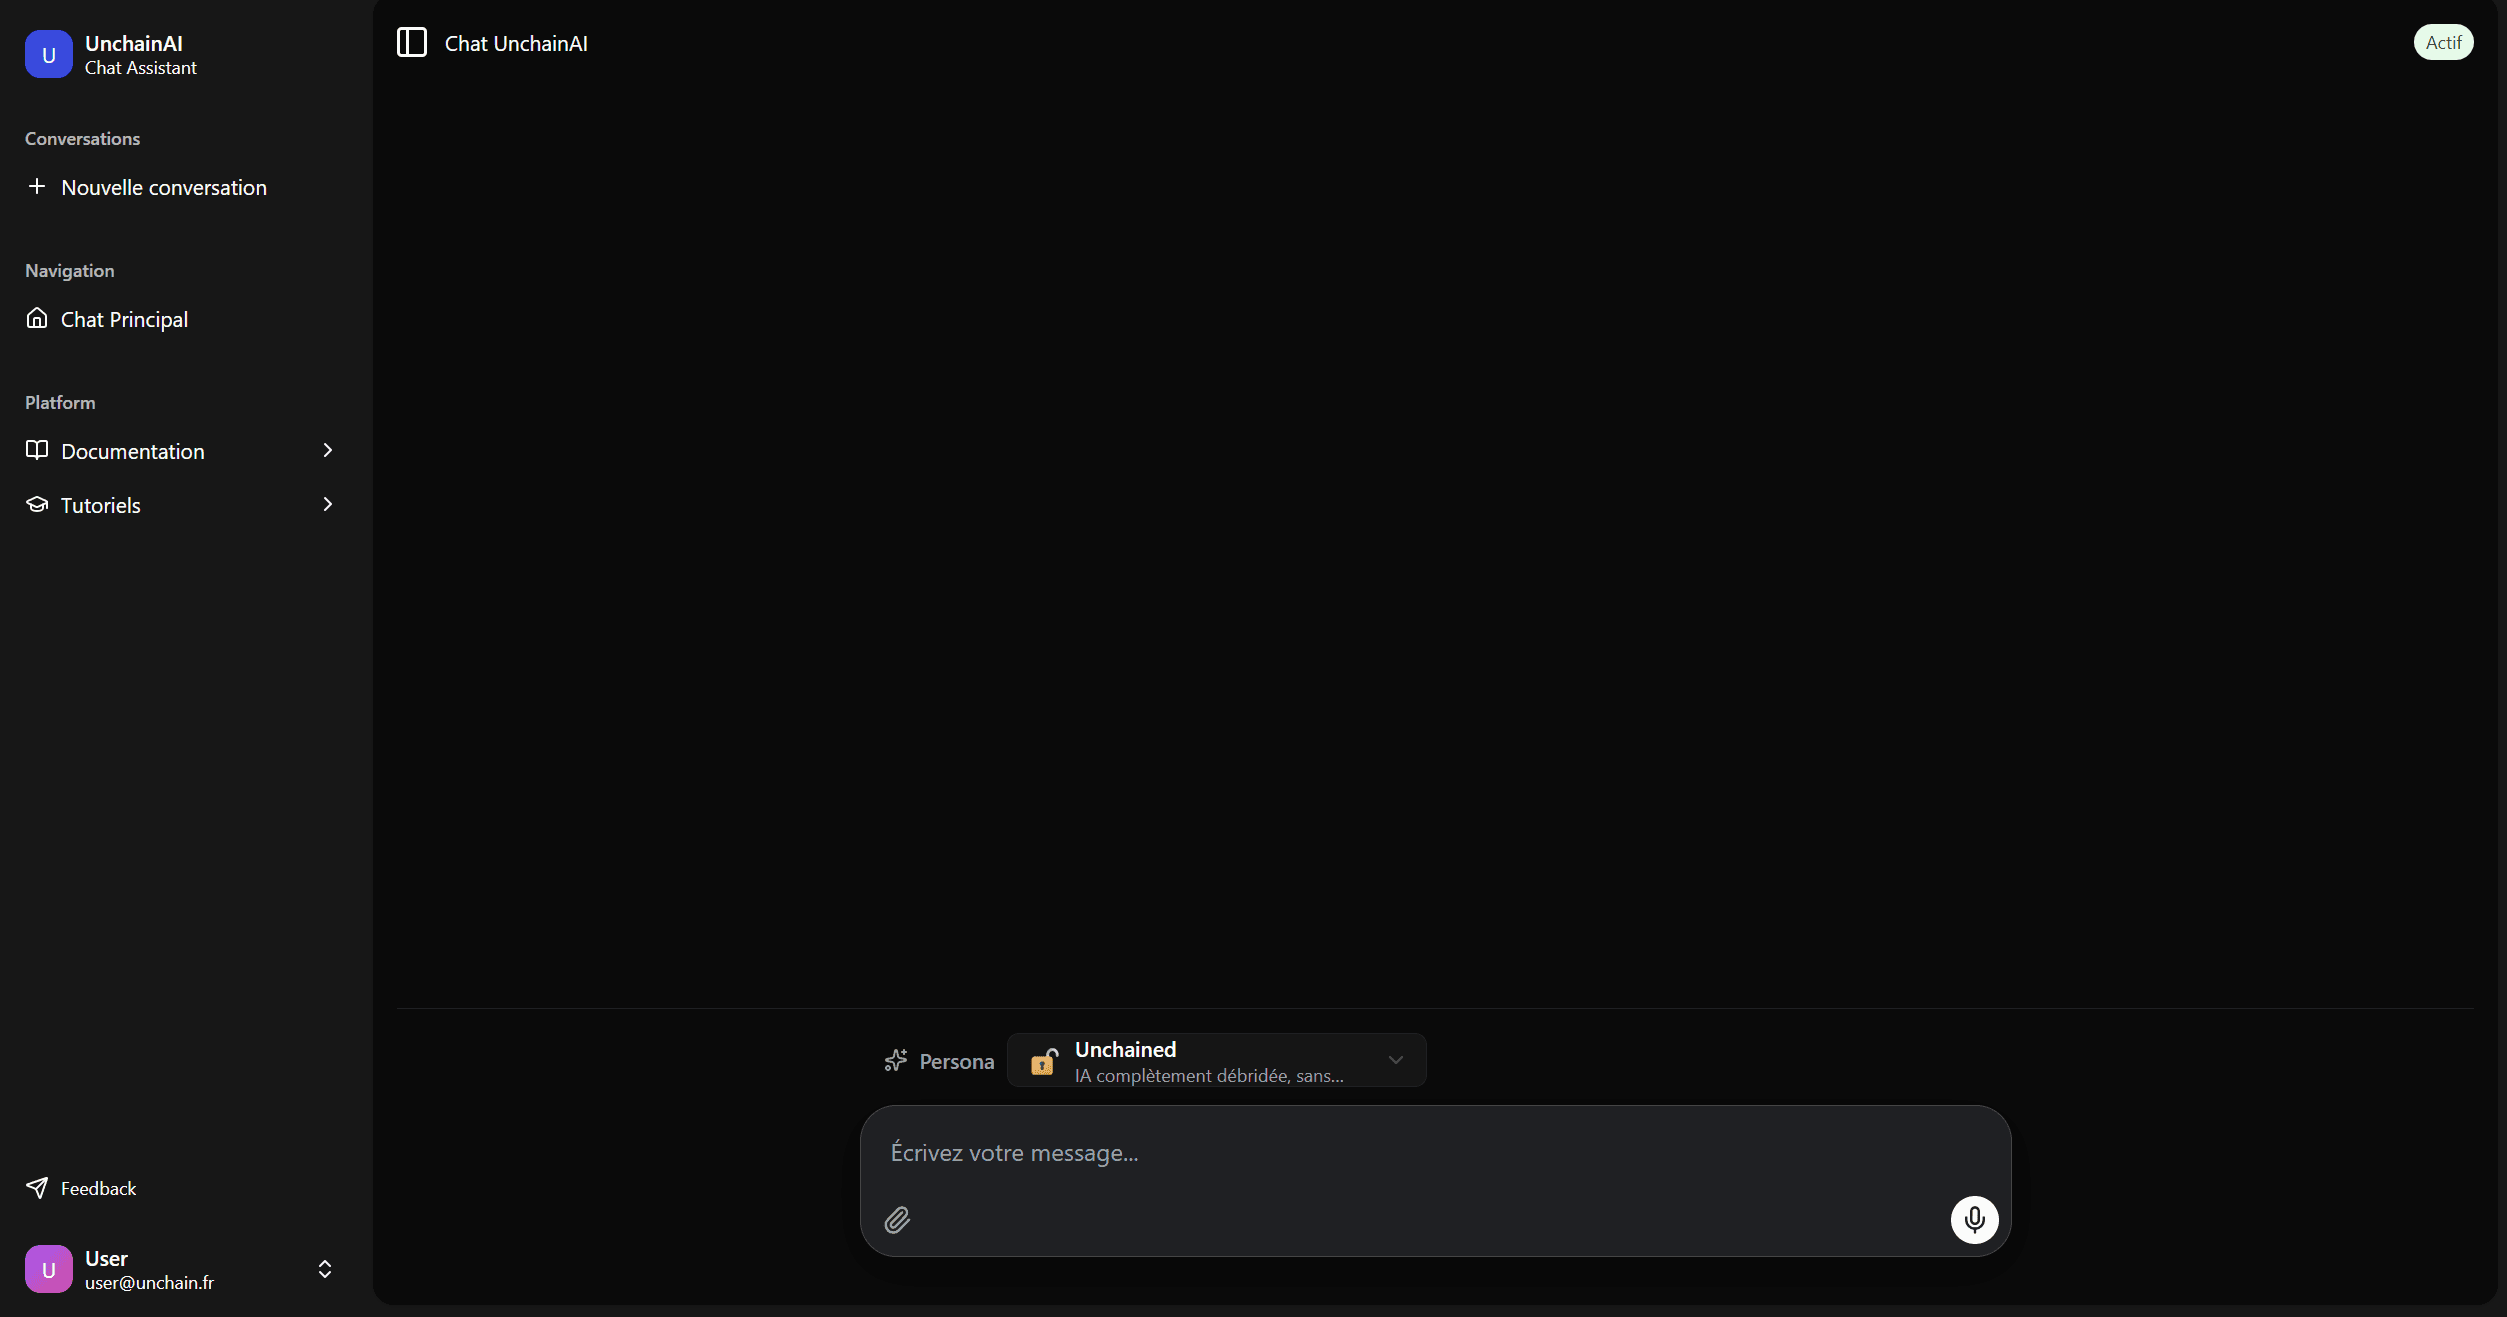
All the power of LLMs, without a single byte leaving the machine.
AI assistants on the market impose a trade-off: sending your documents and conversations to a provider. UnchainAI removes that trade-off. Models, vector index, audio transcription: everything runs locally, on a workstation or a company server.
What UnchainAI does
- Conversation with local models (Llama 3 8B, DeepSeek R1, Mistral) orchestrated by Ollama, with GPU acceleration and streamed responses.
- RAG over your documents: PDF and DOCX files are chunked, embedded and indexed in Qdrant, with semantic search under 100 ms across thousands of documents.
- 12 expert personas, each with its own system prompt and model: cloud (AWS, Azure, GCP), cybersecurity, DevOps, and a website generation module with live preview.
- Multilingual audio transcription with Whisper, executed locally.
Architecture
- Frontend: Next.js 15, TypeScript, Tailwind CSS 4, global state with Zustand.
- Backend: asynchronous FastAPI, JWT authentication, heavy document processing, streaming.
- Data: Qdrant for vectors, automatic conversation persistence, model cache.
- Deployment: Docker Compose and automation scripts (Bash, Python, Batch): the full infrastructure is up in under five minutes, locally or on a cloud instance.
Why local changes everything
- Zero API fees: no variable cost per use.
- Privacy by construction: compatible with GDPR, HIPAA or SOC 2 requirements, since nothing leaves the infrastructure.
- Production-ready: CPU and GPU monitoring, structured logs, cache management.
Open source
The project is released under the Apache 2.0 licence and was built solo from end to end: backend, frontend, indexing, deployment.